Start with the data, not the dashboard
Managing security data at enterprise scale requires a disciplined, repeatable approach. Organizations often struggle with massive data ingestion costs, inconsistent log normalization, complex retention rules, and deteriorating analytics rule quality. By treating data management as a core engineering pipeline rather than an administrative afterthought, security operations teams can control expenses while improving threat detection fidelity. This guide walks through the architecture, implementation steps, security considerations, and operational checklists necessary to deploy a unified data strategy across your Azure landing zones.
Retention and transformation choices
Architecting a governed security data pipeline across collection, normalization, retention, and downstream detection is essential for maintaining visibility in modern cloud environments. A sound adoption decision must carefully consider identity management, network boundaries, deployment automation, logging standards, data classification, disaster recovery, and total cost of ownership. Preview capabilities deserve additional attention regarding service limits, API stability, and vendor support commitments.
When security data pipelines lack proper governance, organizations frequently encounter ingestion bottlenecks, unpredictable storage expenses, and compliance gaps. An effective unified data management strategy establishes clear boundaries between operational telemetry and long-term compliance archives. This separation ensures that high-value security logs remain easily queryable for threat hunters while lower-value diagnostic data is filtered or tiered cost-effectively.
Detection quality versus cost
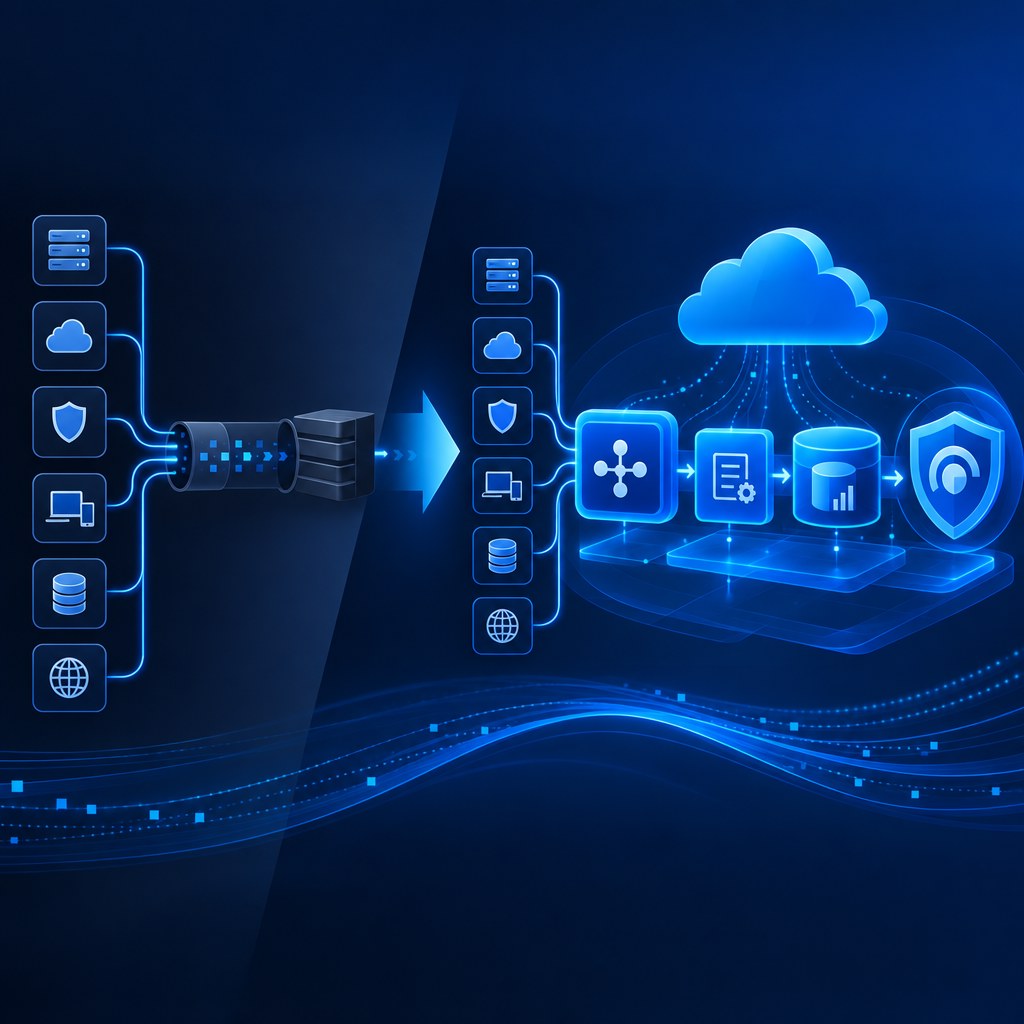
The diagram above illustrates a conceptual implementation sequence rather than a rigid claim that the service exposes these five steps as native, isolated product features. Architects should adapt this flow to align with their organization’s specific enterprise landing zone design and cloud governance model. Each stage in the pipeline serves as a critical control point for data validation, enrichment, and filtering.
Data access and RBAC
Deploying unified data management successfully requires breaking the process down into manageable, testable checkpoints. Each phase of the blueprint below defines distinct operational responsibilities and failure modes.
Inventory sources
Define owners, expected inputs and outputs, failure modes, access controls, and validation evidence before production rollout.
Standardize schema
Map disparate log formats to standard tables using transformation rules to ensure consistent parser behavior and query performance.
Apply collection filters
Discard noisy, low-value telemetry at the ingestion boundary to optimize storage consumption without sacrificing visibility.
Model retention costs
Establish tiering strategies between active analytics storage, interactive retention, and long-term cost-efficient archiving.
Inventory sources
Inventory sources represent a foundational design and operational checkpoint. Security teams must document every data feed originating from multi-cloud resources, SaaS platforms, and on-premises environments. Define the system owner, expected input volumes, output destinations, potential failure modes, access controls, and validation evidence required before authorizing production rollout. Documenting the trade-off between fully managed native connectors and custom ingestion mechanisms ensures that maintenance overhead remains sustainable.
Standardize schema
Schema standardization ensures that analytical queries can process logs from diverse vendors without custom parsing overhead. Implement transformation rules at ingestion to map raw events into standardized tables. Define the owner, expected schema structure, failure modes, access controls, and testing evidence required prior to deployment. Evaluating the trade-off between upfront ingestion transformation and downstream parsing allows architects to balance ingestion compute costs against query-time performance.
Apply collection filters
Unfiltered data ingestion rapidly inflates operational expenditure. Applying collection filters at the edge allows security teams to drop heartbeat logs, routine health checks, and redundant telemetry before storage allocation occurs. Define the owner, expected filtering criteria, failure modes, access controls, and verification evidence before production rollout. Documenting the trade-off between aggressive cost reduction and potential loss of forensic context is critical during this phase.
Model retention costs
Retention modeling requires balancing regulatory compliance mandates against financial constraints. Define active retention windows for high-speed threat hunting and extended retention policies for archival compliance. Establish the owner, expected storage volume projections, failure modes, access controls, and verification evidence prior to production rollout. Documenting the trade-off between interactive analytic retention and archived search tier latency helps set realistic expectations with stakeholders.
Test detection coverage
Testing detection coverage ensures that data normalization and filtering do not inadvertently blind analytics rules. Validate that custom and out-of-the-box detection queries continue to trigger accurately after pipeline modifications. Define the owner, expected test outcomes, failure modes, access controls, and validation evidence required before production rollout. Documenting the trade-off between synthetic test accuracy and production parity ensures reliable threat detection.
Detection coverage
Robust security and governance form the bedrock of any enterprise data management strategy. Use Microsoft Entra identities wherever supported, enforce principle-of-least-privilege role-based access control (RBAC), manage sensitive secrets securely in Azure Key Vault, establish explicit network trust boundaries, and maintain structured audit logs for all administrative actions. Define a clear data retention policy, mandatory approval gates for consequential configuration changes, and assign an accountable incident response owner.
Furthermore, never expose administrative credentials, connection strings, or tenant secrets within source code repositories, deployment scripts, or unencrypted telemetry streams. Implement continuous compliance monitoring using Azure Policy to detect configuration drift across workspaces, data collection rules, and storage accounts.
Retention costs
Operational readiness requires thorough testing under adverse conditions. Engineers must test retry mechanisms, partial ingestion failures, upstream throttling, temporary region unavailability, and rollback procedures. Ensure that side-effecting automation scripts and configuration deployments are strictly idempotent. Collect comprehensive telemetry covering latency, error rates, consumption metrics, and upstream dependency health.
Create a detailed operational runbook that explicitly outlines how to safely disable, bypass, or isolate the data management feature without interrupting unrelated security workloads or blinding frontline analysts during an active security incident.
Operational ownership
Controlling costs in cloud-native security platforms requires continuous financial vigilance. Estimate infrastructure costs, API usage charges, storage consumption, cross-region networking fees, and tiering expenses accurately. Always benchmark a representative production-scale workload rather than projecting costs solely from vendor marketing examples or small test environments.
Establish strict budget alerts, assign precise cost center tags to all associated resources, and review consumption trends monthly. When evaluating preview products, verify billing meters, pricing models, and service level agreements (SLAs) thoroughly before committing to production adoption.
The practical takeaway
Microsoft Sentinel Unified Data Management should be rigorously evaluated as an essential architectural capability rather than a simple feature checkbox. Begin by establishing clear operational requirements, validate the current service contracts and API limits, and adopt the framework incrementally using empirical evidence gathered from a controlled pilot environment. By maintaining disciplined engineering standards, security architects can build resilient, cost-effective, and highly responsive threat detection operations.
Further reading
Consult the Microsoft documentation and official announcement to verify the latest version details, regional availability, and related release notes before proceeding with production publication.
More articles on Cloud Security are available in the blog archive.